As I continue to study my experimental home R&D A.I. server (https://ai.sauer.studio/), users of the system keep asking it questions that would be much better suited to search engines — such as, for instance, the open hours of a local business. My system wasn’t designed to answer those sorts of questions; I’m running a locally-hosted LLM, one much smaller (and therefore more environmentally sustainable) than those of Anthropic Claude, or ChatGPT, or Google Gemini. But I’m upset by my realization that users really don’t know how to use an A.I. effectively.
I’ve studied A.I.s in depth in the past few years, and so I know well that A.I.s are more like “little Wikipedias” than “Googles.” They are built upon a collection of documents (generally at a relatively introductory level, and often at least a year out of date—sometimes more). So they’re not good at detailed expertise, local, or time-sensitive queries. Even the largest generative AIs (which support trillions of parameters, whereas ours consists of only 27 billion) aren’t great at such prompts. Asking “wrong” questions — such as news about the U.S./Iran war, or information about local venues, or details about people who aren’t famous — increases the likelihood of hallucination (incorrect answers), enormously.
Ursula Le Guin, in her 1969 novel The Left Hand of Darkness, has a wise character explain to our narrator “the perfect uselessness of knowing the answer to the wrong question.” I believe there is great wisdom in understanding what and how to ask a source, when researching (as my friends in ‘prompt engineering’ have studied for a while). It means, often, knowing how to best use tools. Le Guin’s novel points out something reflected in my own experience, from decades of library and archival research — no matter how much we might want a single all-encompassing knowledge source, that’s not how real knowledges usually operate. That’s why I trust my university library’s several hundred specific research databases more than Google Scholar.
Robert Pirsig, in his 1974 fictionalized autobiography Zen and the Art of Motorcycle Maintenance raises a similar concept, when he discusses “Mu,” a term he takes from Zen Buddhism. In his telling, “Mu” is an answer designed to negate a bad question. It isn’t a “yes” or a “no,” he argues, but instead a pointed rejection of implicit assumptions within a question itself. He suggests we should all think about answering some questions that way; this week, I wish generative A.I.s were able to do that. I often believe literature contains wisdom I wish 2026 users of generative A.I. had more easily at hand.
But (and here’s the difficulty of building server technologies). It’s easier to change my server, than to change people. (People don’t want to change.) You can tell this by the fact that Le Guin’s and Pirsig’s books aren’t widely read today, and that their contributions, though perhaps recognized five decades ago, haven’t become central to our thinking today.
So. After considering the problem for a while, I decided that I probably should just add a full Internet search engine to the little Linux server I keep in my home laundry room.
I needed my own Google — sort of.
So this morning, I built one. It took about half an hour to launch a comprehensive Internet search engine.
(If that sounds difficult, you should really read about how amazing modern open source containerization technologies are.)
I couldn’t just have my A.I. rely on search APIs offered by Google, DuckDuckGo, Bing, or Wikipedia. Those organizations provide limited access to users, but a local AI needs lots of access — more than companies generally offer to rivals (even small ones, such as my own little site). My site could negotiate long-term contracts with existing search engines, paying monthly fees for our usage. But I didn’t want that. I’d rather run my own search engine; that’s part of the whole point of locally-hosted servers.
So I’ve launched “Sauer Studio Search,” as I call it (at https://search.sauer.studio/). It really only took a half-hour to launch, since it’s just an implementation on Linux/Docker of the open source metasearch system SearXNG. (When you understand modern cloud computing and know the rich, open source ecosystem to stand upon the shoulders of, this sort of thing is easier than it sounds.)
I then connected Sauer Studio A.I. to this search engine, and turned on my Open-WebUI server’s “Web Search” feature, to consult my local search engine, by default. Now, when you ask my A.I. a question about any topic, when the internal LLM decides that it doesn’t know enough about a user’s query, it will search Internet web pages, read top ten results, and use the information from those pages to inform its answers.
This will fundamentally transform Sauer Search A.I., from a small, local knowledge base to one informed by the entire Web. (I just searched the A.I. for information about a small, family-owned doughnut shop near my neighborhood high school, and it answered well.) But I wish that our users understood the implications of such a setting. Web Search will lower my A.I.s use of specific, detailed, local knowledge bases in its answers (it may prefer general information from the Internet). And such settings are important to every research tool in the modern world. I make this choice hesitantly, but it seems the better way to cope with users who ask “bad questions.” I think this will allow people who try my system to get answers more in keeping with those from corporate frontier genAIs. I wish I could teach users, as bibliographic instruction specialists at research libraries used to; but so far, people just want everything in one place. As unwise as that may be.
I should be clear that I’m not trying to “shame” any users. I don’t think the behaviors I’m seeing among A.I. users come from laziness or sloppiness, or any personal failing of individuals. Instead, the issue comes from larger social knowledge about generative A.I.s, their internal knowledge ideologies, and how they connect to information repositories. I think we should work, as a field, to improve that general understanding, by educating everyone, as generative A.I.s become more widespread.
I will work to customize the search engine over the next few weeks, adjusting the sources it consults for answers. All search engines have ideologies — those of you who know me in person have heard diatribes against choices like those made by Google. This one will have impeccable privacy for users. It will show “Lake Ontario” on its map (to follow International Hydrographic Organization Technical Resolution A.4.2.6. and the United Nations Resolution on the Standardization of Geographical Names guidelines). And in the process, I’ll learn more practically how the ‘guts’ inside modern Internet search engines really work.
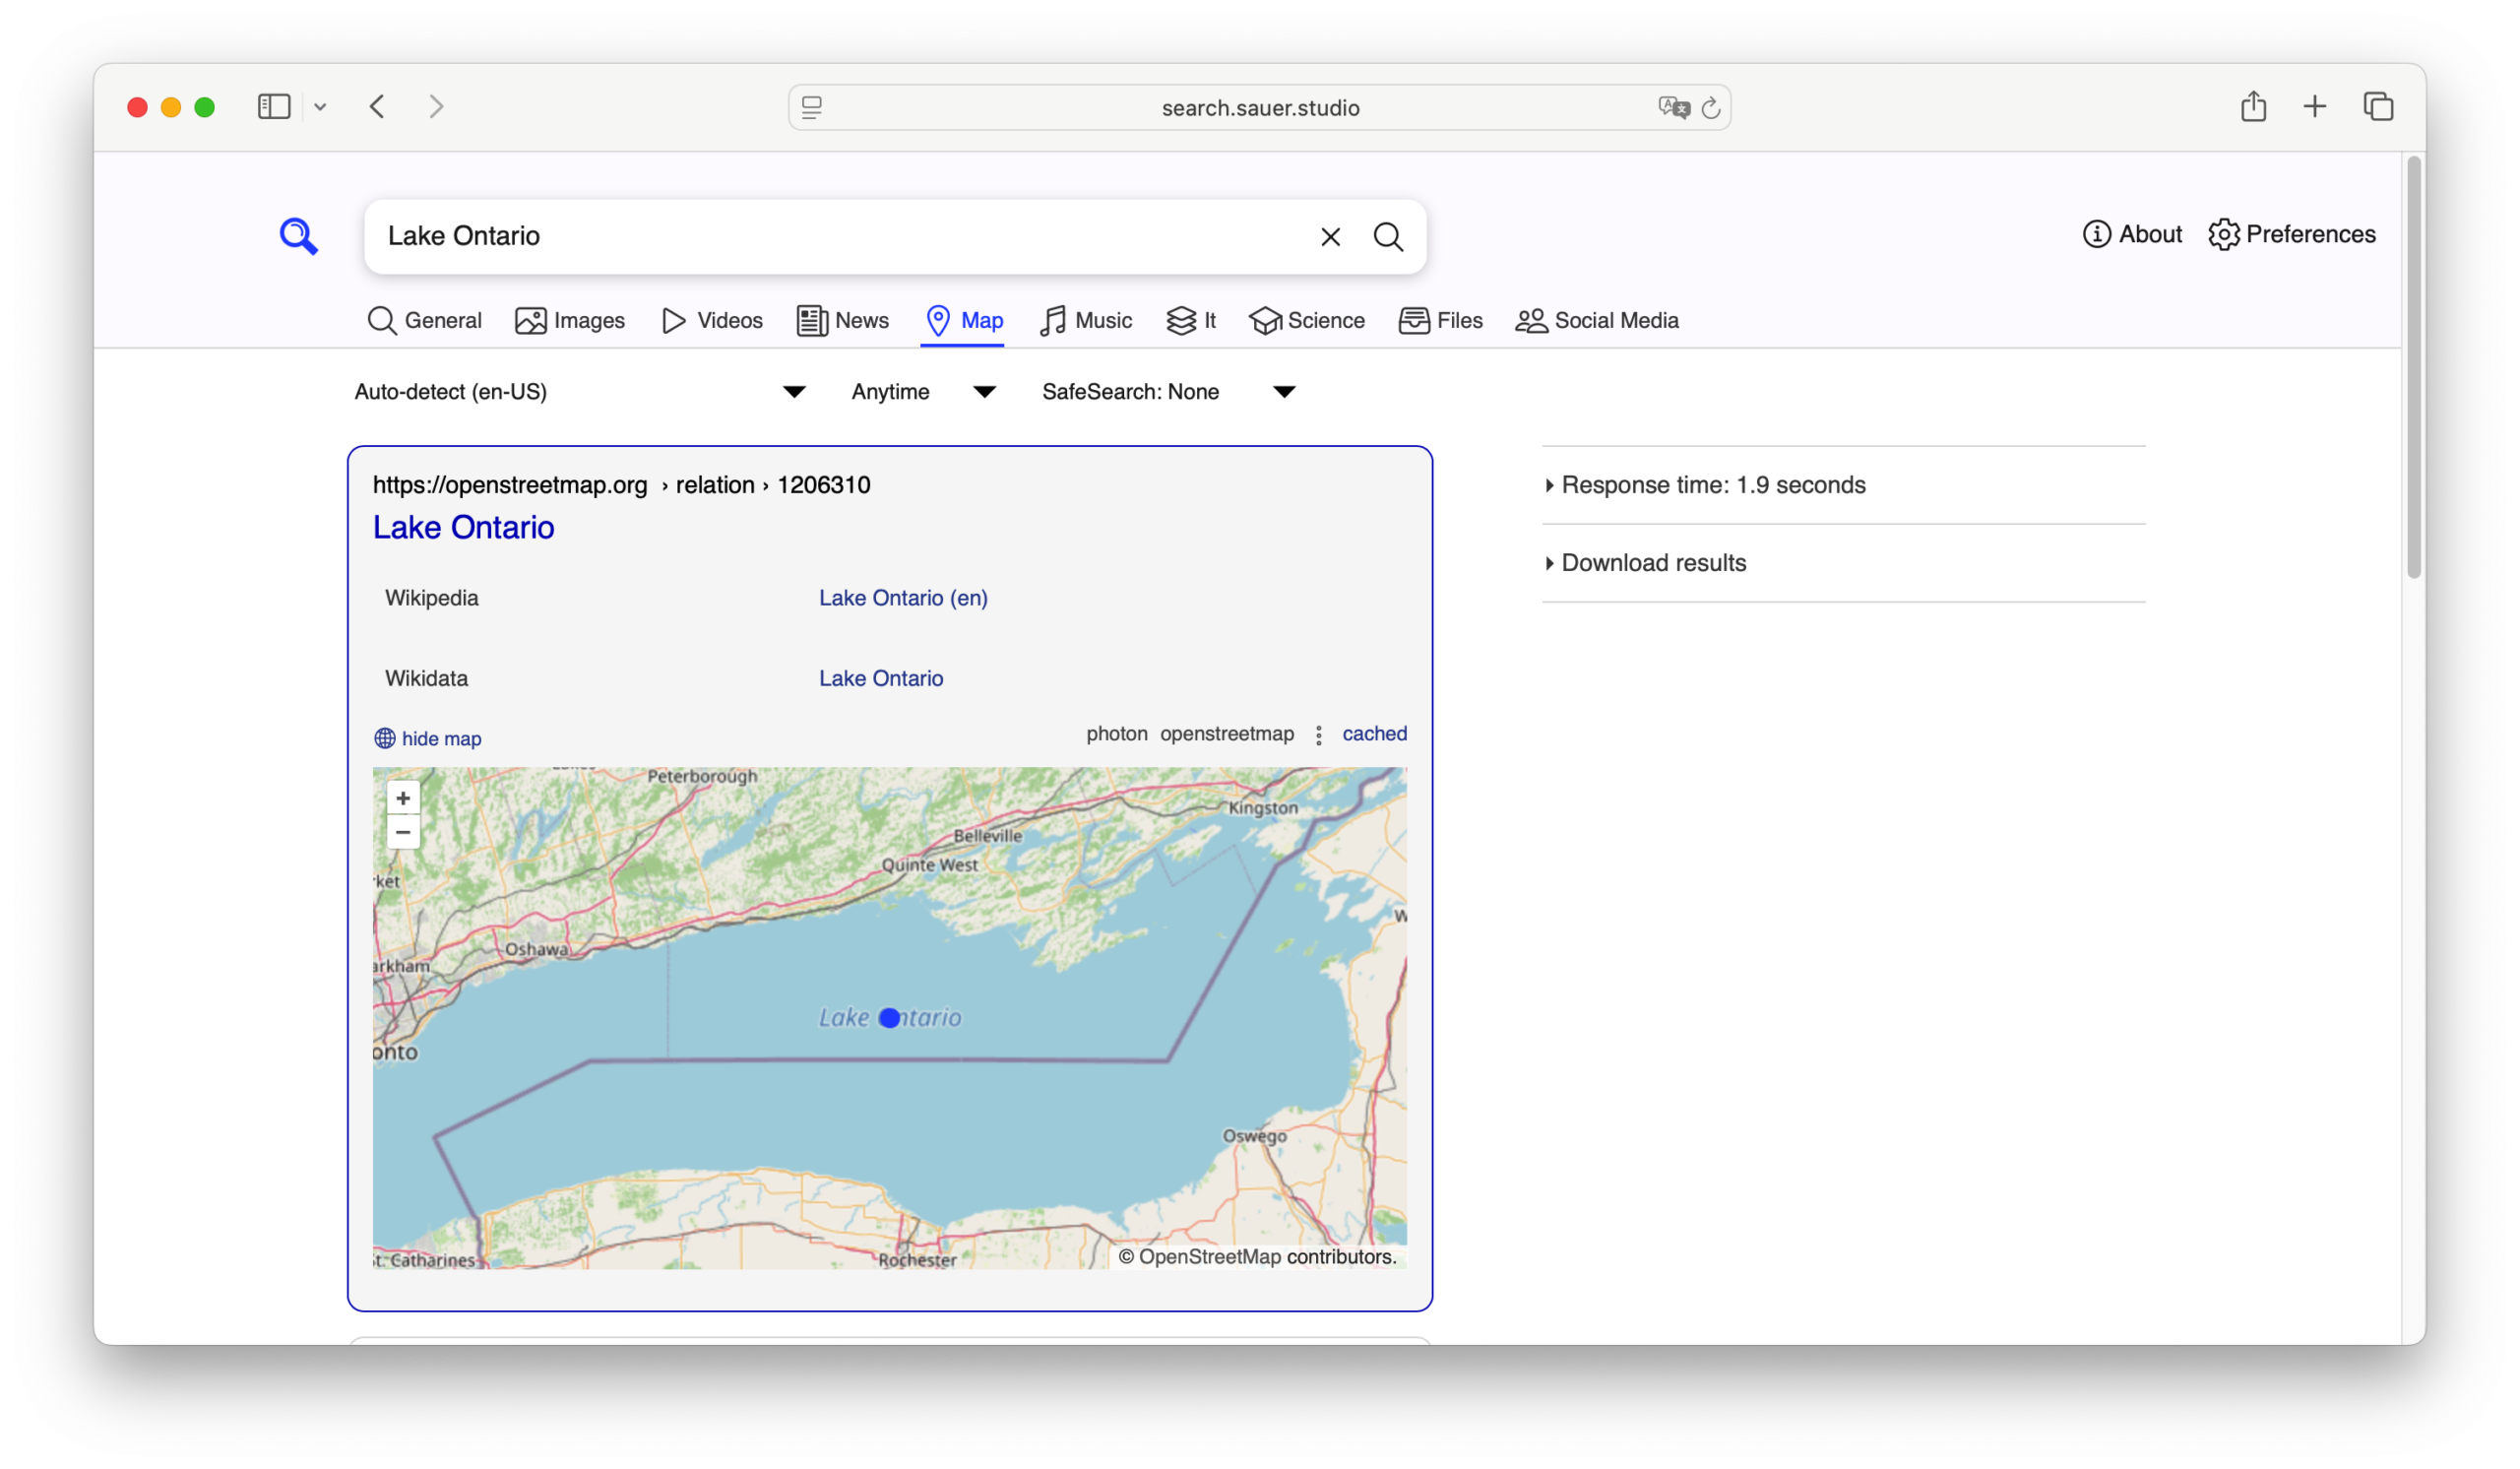
You can give it a try, if you want. https://search.sauer.studio/. (It seems to be working nicely.) And if you use Sauer Studio A.I., it now can search the Internet when it suspects its internal knowledge base isn’t complete.
So. Win win? In a way. Sort of.